# Phala's Recap of TEE.salon Singapore: GPU TEE and more
**URL:** https://collective.flashbots.net/t/phalas-recap-of-tee-salon-singapore-gpu-tee-and-more/3867
**Category:** TEE - Trusted Execution Environment
**Tags:** event, tee-salon
**Created:** [September 24, 2024, 11:42am UTC](https://collective.flashbots.net/t/phalas-recap-of-tee-salon-singapore-gpu-tee-and-more/3867 "2024-09-24T11:42:39Z")
**Posts on this page:** 1
**Page:** 1
### Author:  [@h4x3rotab](https://collective.flashbots.net/u/h4x3rotab)
#### Post date: [September 24, 2024, 11:42am UTC](https://collective.flashbots.net/t/phalas-recap-of-tee-salon-singapore-gpu-tee-and-more/3867/1 "2024-09-24T11:42:40Z")
>
The 3rd TEE.salon just happened! With contributions from more than 30 TEE accelerators, there were several interesting talks:
- **Glue and Coprocessor Architectures** - Vitalik (EF)
- **Framework for trustless TEE chip design** - Michael Gao (Fabric Cryptography)
- **Benchmarking and evaluating GPU-based TEEs -** Hang Yin (Phala)
- **DCAP library v4: A unified interface to verify TEEs on-chain** - Zheng Leong Chua (Automata)
Here, I’d like to briefly summarize the key takeaways from the Phala team’s perspective.
# GPU TEE and Performance Evaluation
Besides CPU TEEs, there are now GPUs with full TEE capabilities. This enables trustless, data-intensive applications like AI training and inferencing.
Now there are two available GPU with TEE:
- nVIDIA H100: 94GB VRAM and 3.9 TB/s bandwidth (general access in Q1 2024)
- nVIDIA H200: 141GB VRAM and 4.8 TB/s bandwidth (early bird access in Q3 2024)
Due to its design, GPU TEE introduces some overhead:
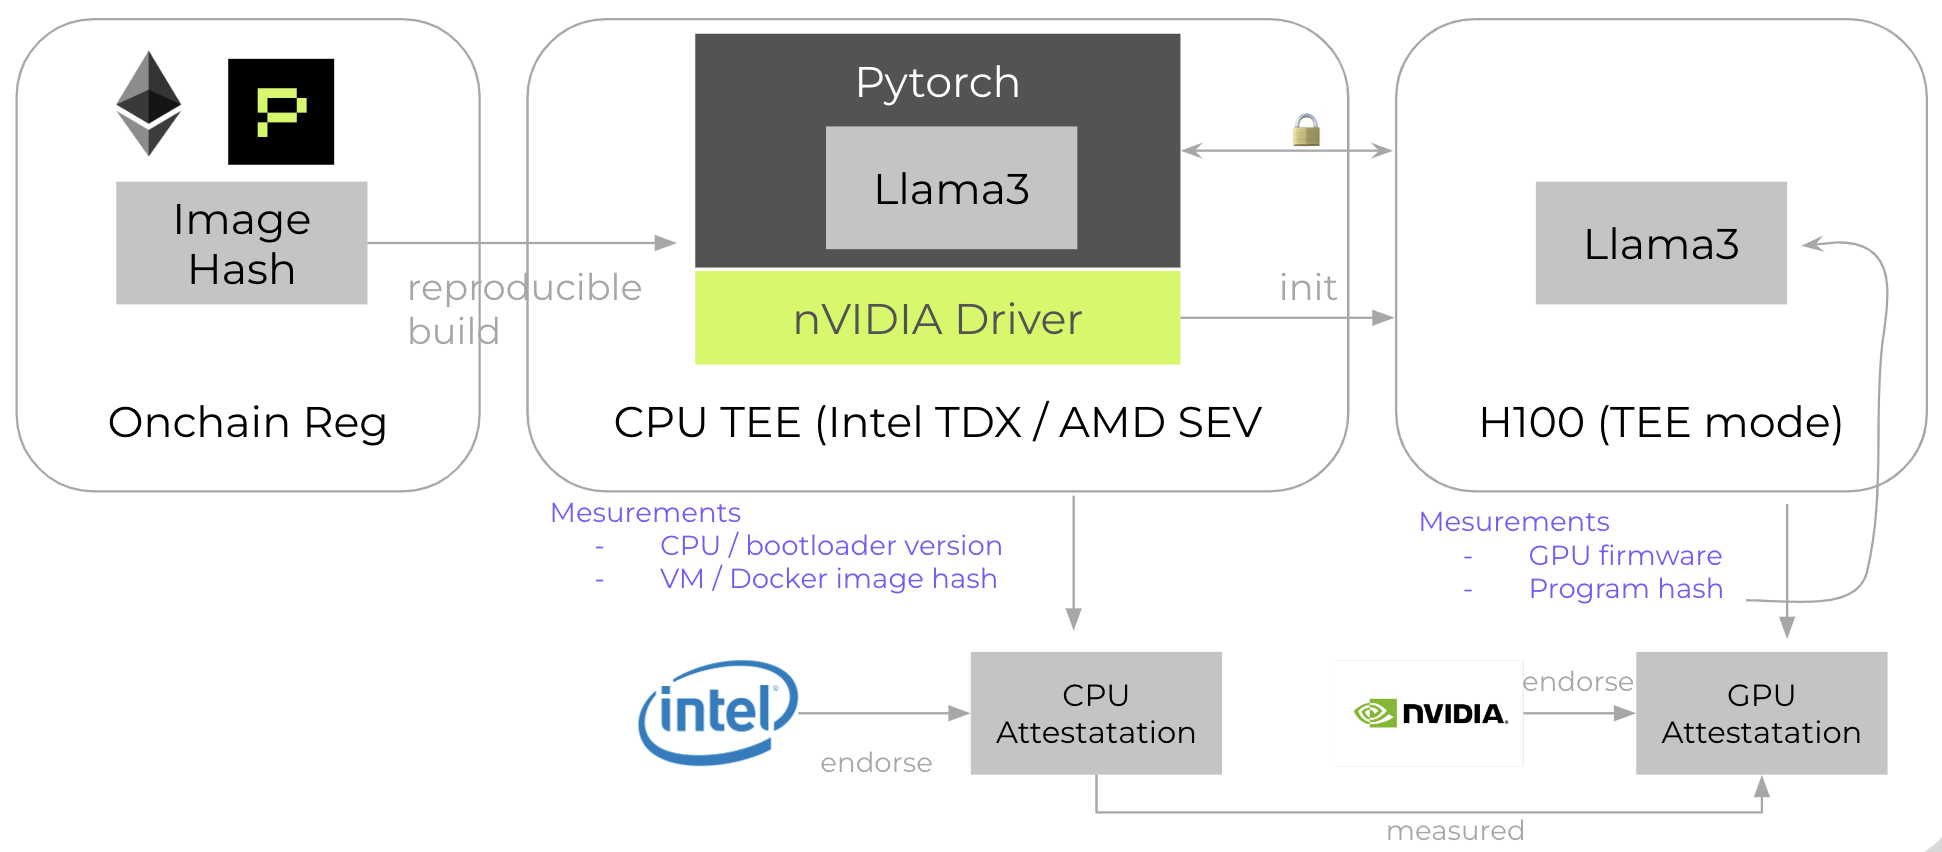
- GPU passthrough to a Confidential VM (CVM)
- Driver in CVM sets up E2E encryption channel between the CVM and GPU
- GPU generates Remote Attestation to bootstrap trust
- Unmodified code can run in CVM to access the GPU
- The encrypted IO is the main source of overhead
Benchmarks using vLLM show that:
- **Throughput overhead** : less than 7% on TPS (tokens per second), less than 3% on QPS
- **Latency overhead** : significant increase in Time to First Token (~20%) but less in Inter-Token Latency (less than 7%)
- **Overhead decreases** with longer sequences or larger models
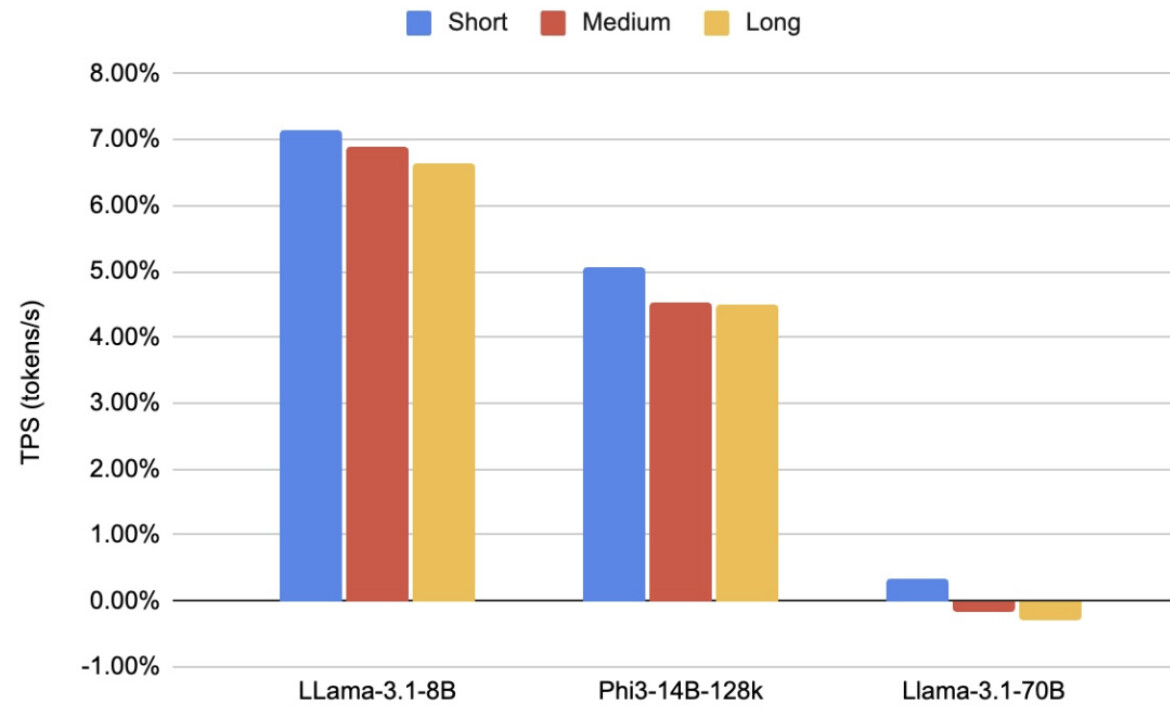
**Conclusion:** GPU TEEs provide a practically viable solution for verifiable and privacy-preserving computation with manageable overhead.
👉 [Full Slides](https://hackmd.io/@h4x3rotab/rJfgObKpC)
# Call to Actions
We are closer than ever to the mass adoption of TEE. The demand is clear, and the supply is emerging. Many pressing challenges are waiting for TEE-based solutions, and the next generation of TEEs promises significantly better performance and developer experience.
However, there is still much work to be done to turn this vision into reality. Here are our key calls to action:
1. **Need for Democratizing TEE**
2. **Build a Decentralize Root-of-Trust**
3. **Build TEE Ecosystem Together**